How We Built an AI-Assisted Crypto News Platform: CryptoResearch.news and Blockblatt
How we built an AI crypto news platform ingesting ~280 items daily across CryptoResearch.news and Blockblatt, with deduplication, validation, and human review.
The 24/7 Editorial Challenge in Crypto Media
Digital asset markets operate continuously without open or close bells. Protocol updates, regulatory filings, exchange notices, on-chain events, and security disclosures break around the clock across an unstructured, fragmented web. For a modern crypto publication, keeping pace with this volume in real time presents an operational bottleneck that traditional editorial workflows cannot handle cleanly.
The Bottleneck of Fragmented Ingestion
An editorial desk attempting to deliver timely market coverage must monitor hundreds of disparate feeds simultaneously:
- RSS Feeds: Crypto news outlets, foundation blogs, protocol roadmaps, and official press releases.
- Telegram Channels: High-velocity project updates, direct developer announcements, and real-time community alerts.
- X Accounts: Founder statements, security researcher disclosures, and breaking market threads.
When editors manually parse raw feeds, check for duplicate reporting, summarize events, and translate stories for foreign-language audiences, operational latency climbs quickly. Editorial fatigue leads to missed stories, inconsistent coverage, and high overhead costs.
Human-in-the-Loop vs. Fully Automatic Publishing
To increase output, some operations experiment with fully automatic publishing. Pushing raw AI output straight to production creates severe editorial hazards: models can hallucinate details, misinterpret technical token mechanics, pass through unverified marketing claims, and publish redundant variations of the same underlying story directly to readers.
The system built for CryptoResearch.news (English) and Blockblatt.com (German) solves this challenge through a strict human-in-the-loop architecture. The goal is high-throughput, low-latency news delivery without compromising editorial integrity. By offloading feed monitoring, deduplication, and initial drafting to background workers, editors can evaluate structured drafts in seconds rather than chasing feeds across multiple apps. Human editors retain complete control over every single item that reaches the public.
Two Sites, Two Languages: CryptoResearch.news and Blockblatt
CryptoResearch.news serves an international, English-speaking audience, while Blockblatt.com provides coverage for German-speaking readers. Instead of maintaining two separate codebases or running parallel CMS deployments, both properties run entirely from a single shared repository (/home/user/cryptoresearch-app). This unified codebase allows shared ingestion, storage, and processing infrastructure to serve both domains efficiently.
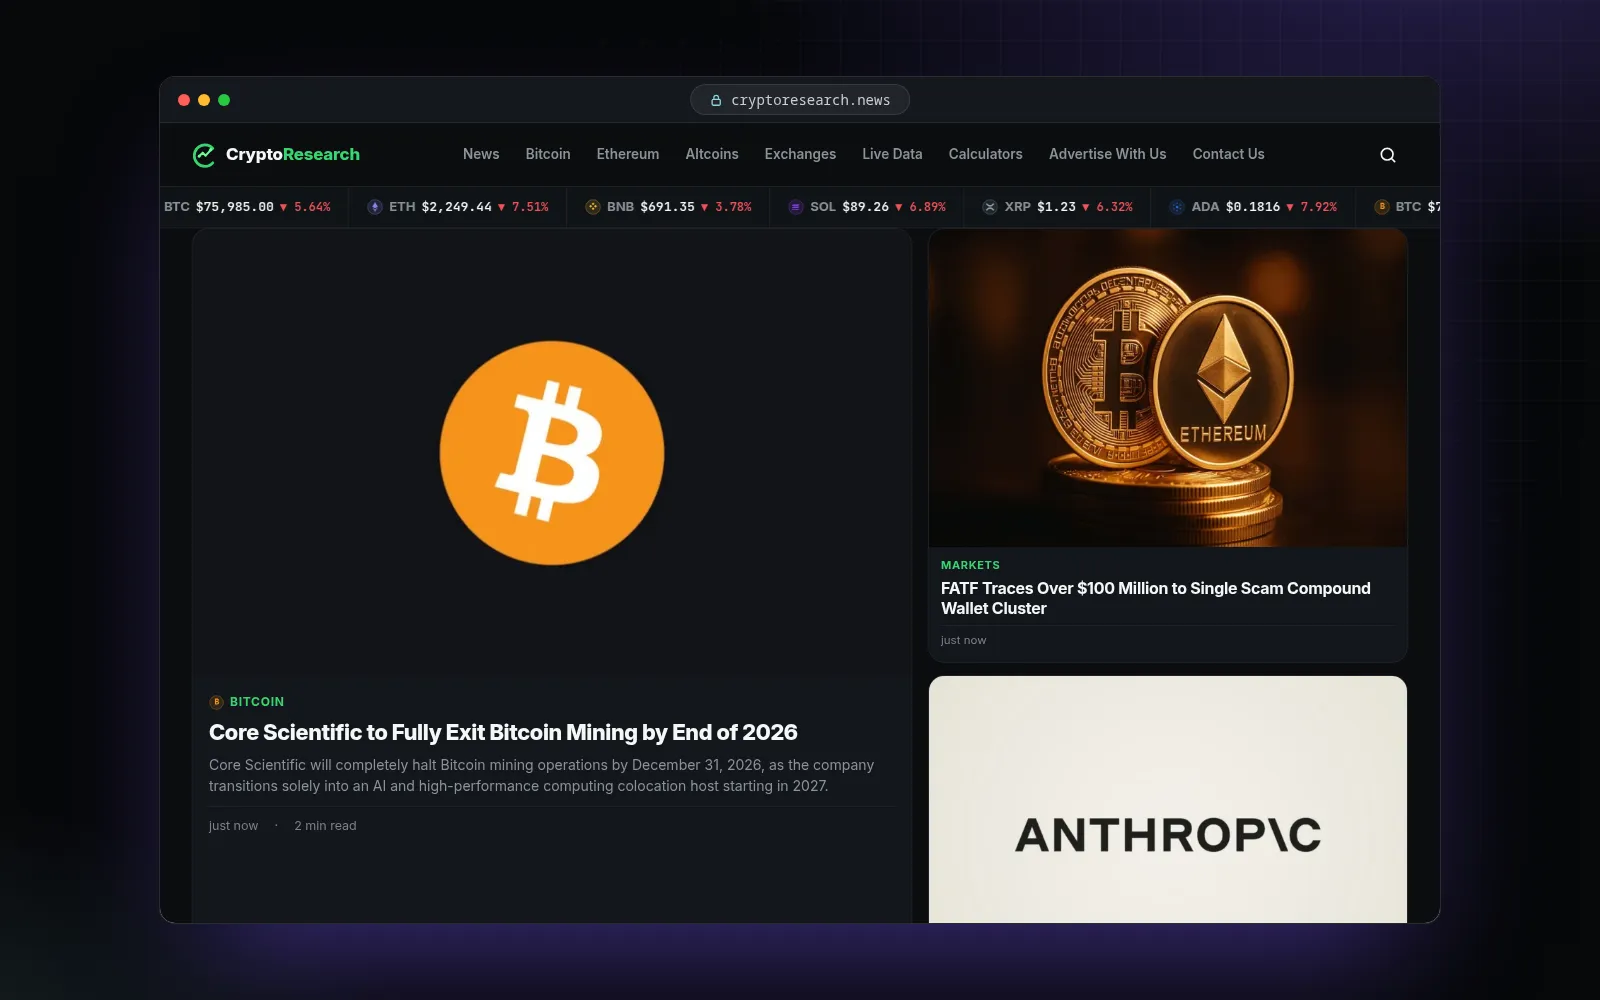
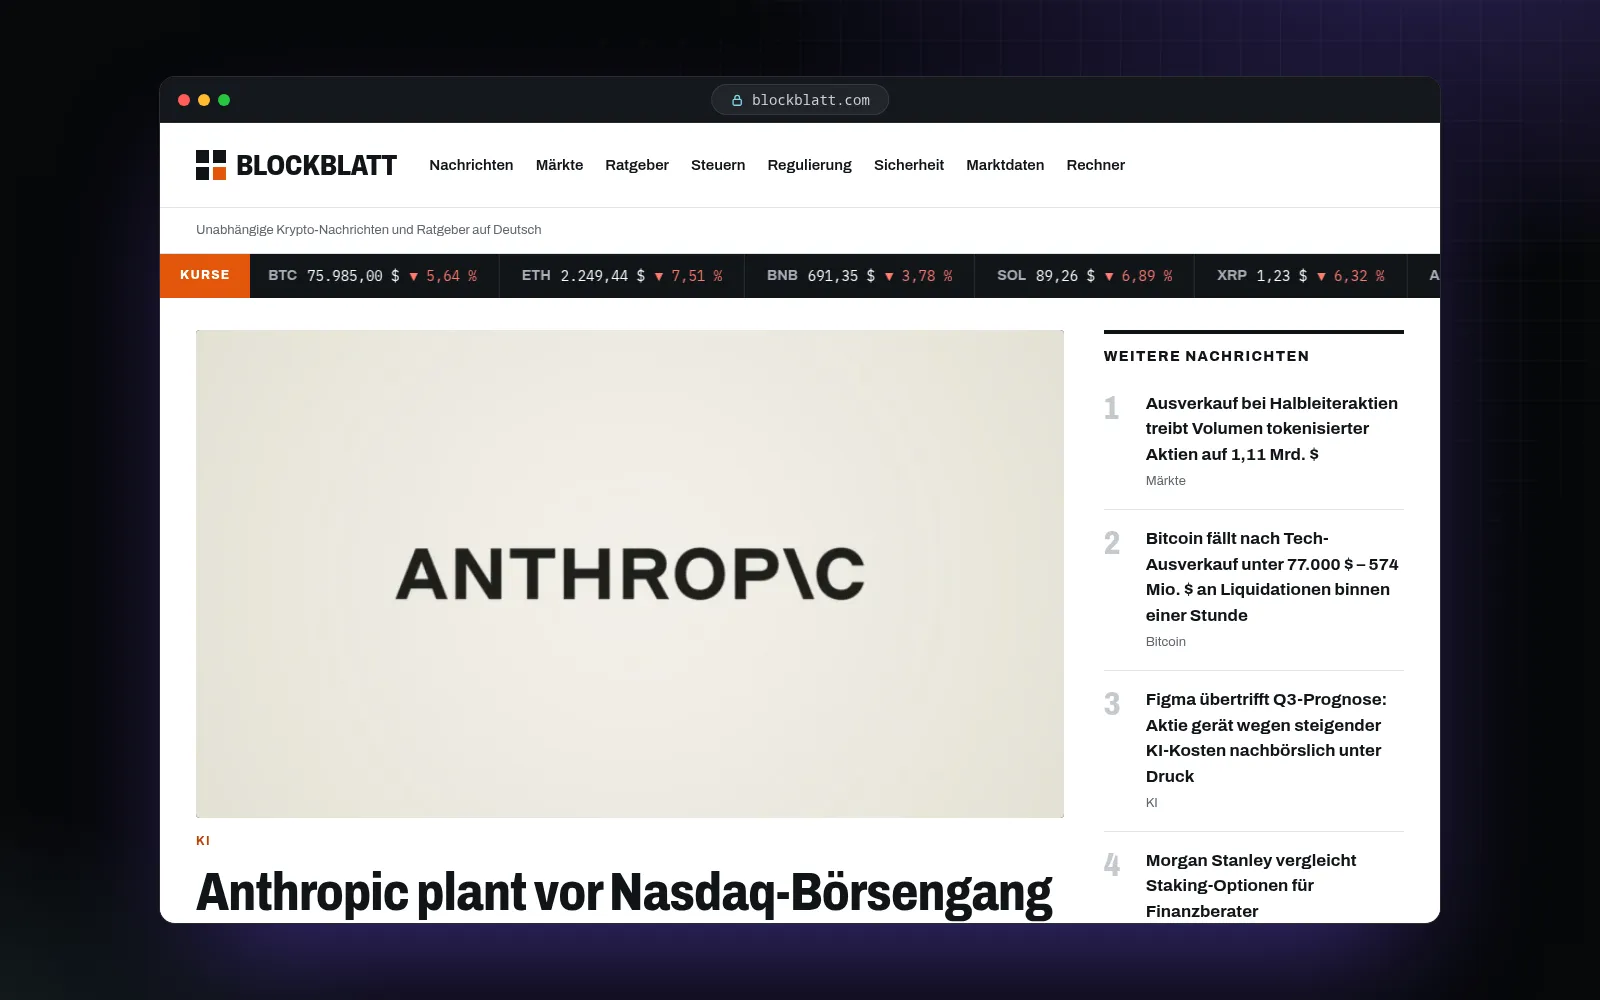
Unified Repository, Locale-Aware Data Model
Language requirements are handled at the data model level rather than by splitting the application into distinct services. Built with Next.js, Prisma, and PostgreSQL, the database layer manages localized drafts, translations, and domain routing within unified entity tables:
// Conceptual Prisma schema structure
model Post {
  id            String       @id @default(cuid())
  locale        String       // "en" | "de"
  title         String
  slug          String       @unique
  content       String
  canonicalId   String?
  status        ReviewStatus @default(PENDING_REVIEW)
  publishedAt   DateTime?
}
This structure allows the backend to treat English and German items as linked records while preserving locale-specific slugs, metadata, and editorial states.
The Pitfalls of Unverified Web3 Translation
Direct, unverified machine translation routinely fails in crypto media. Web3 reporting relies on standardized English technical terminology that does not translate cleanly using standard translation APIs:
- Jargon distortion: Core industry terms like slashing, airdrop, cold storage, liquidity pool, and yield farming are often translated into literal, unnatural German phrasing that technical readers reject.
- Link and entity corruption: Unchecked automated translation passes frequently strip anchor links, alter source URLs, or misinterpret network tickers and protocol names as regular vocabulary words.
For Blockblatt.com, the system requires translation outputs to pass verification checks—ensuring designated crypto terminology remains in English and all original links are retained—before moving to the editorial queue.
The Pipeline Architecture: Ingesting ~280 Items a Day
The ingestion engine monitors incoming crypto developments across multiple distribution channels, bringing in roughly 280 raw items every day across RSS feeds, Telegram channels, and X accounts. Rather than treating these inbound feeds as a single monolithic polling process, the architecture splits ingestion into decoupled worker loops managed by server-level cron jobs.
Independent Polling Loops
Different feed formats operate on distinct release cadences and rate-limit constraints. Isolating the collection loops ensures that network latency or upstream downtime on one protocol never stalls the remaining feeds. The studio configures these passes with dedicated schedules:
| Ingestion Source | Check Interval | Operational Focus |
|---|---|---|
| Telegram channels | Every 3 minutes | Capturing breaking updates and announcements directly from channel streams |
| X accounts | Every 15 minutes | Polling tracked public profiles while respecting platform query budgets |
| RSS feeds | Every 2 hours | Parsing structured syndication feeds from industry publications |
Each loop operates with strict fault isolation. Failures are handled on a per-item and per-source basis: if an RSS endpoint returns an invalid XML payload or an external host times out, the parser logs the incident and proceeds to the next record. A single dead feed never aborts the execution run.
Concurrency and Transactional Run Locks
Because scheduled jobs run continuously, high upstream activity or slow response times could lead to overlapping runs where two worker processes attempt to poll the same source concurrently.
To eliminate race conditions, the engine uses PostgreSQL and Prisma 6 with strict isolation levels. When an ingestion pass starts, it attempts to claim the current execution cycle inside a serializable transaction. If an active run is already flagged in the database for that source group, the transaction immediately releases and the worker process terminates without doing redundant work:
// Worker lock claimed inside a serializable transaction
const activeRun = await prisma.$transaction(async (tx) => {
  const running = await tx.ingestionRun.findFirst({
    where: { sourceGroup: 'TELEGRAM', status: 'RUNNING' },
  });
  if (running) return null;

  return tx.ingestionRun.create({
    data: { sourceGroup: 'TELEGRAM', status: 'RUNNING', startedAt: new Date() },
  });
}, {
  isolationLevel: Prisma.TransactionIsolationLevel.Serializable,
});

if (!activeRun) process.exit(0);
Once the transaction locks the slot, the worker ingests pending records, stages raw payloads for deduplication, and marks the run complete.
Dedupe First, Model Second: Protecting the API Budget
When processing high-velocity data streams, calling a large language model on every incoming payload is an expensive anti-pattern. Token billing, external rate limits, and inference latency make AI processing the most resource-intensive phase of any automated pipeline. The core engineering rule in our ingestion architecture is straightforward: never send redundant text to an LLM.
The Two-Stage Deduplication Gate
Before an item reaches the drafting phase, it must pass through an immediate database-level filter. Incoming items from RSS feeds, Telegram channels, and X accounts are checked against existing records using two primary identifiers:
- Canonical URL Validation: The incoming URL is normalized and queried against stored source links in PostgreSQL via Prisma. If the URL has already been recorded, the pipeline drops the payload immediately.
- Content Hashing: Different aggregators and channels often publish identical text under different URLs. The background worker generates a SHA-256 hash of the normalized headline and primary text block. If that content hash matches an existing record in the database, the item is discarded without triggering an API call.
// Deduplication check prior to model dispatch
const existingItem = await prisma.rawNewsItem.findFirst({
  where: {
    OR: [
      { sourceUrl: item.normalizedUrl },
      { contentHash: item.contentHash }
    ]
  },
  select: { id: true }
});

if (existingItem) {
  return; // Terminate early: zero LLM tokens consumed
}
Mitigating Breaking News Surges
In crypto media, breaking developments trigger simultaneous reports across dozens of outlets within minutes. A single market event or regulatory update will hit multiple RSS feeds, Telegram broadcasts, and social accounts at the same time. Ingesting ~280 items a day across diverse channels means a high percentage of raw alerts cover identical subject matter.
Without pre-model deduplication, the system would repeatedly call the LLM to rewrite the same story, draining API credits and clogging the background job queue. Running an indexed database query takes a few milliseconds, whereas invoking a model takes seconds and costs real compute budget.
Filtering out duplicates at the door ensures the rewriter processes only genuinely distinct stories. Applying this lean system design keeps operational expenses predictable, a principle we cover in our guide on web app development cost.
AI Drafting and Validation: What the Model Does and Refuses
In the production setup for CryptoResearch.news and Blockblatt, the drafting phase processes raw incoming updates into structured editorial drafts using Google Gemini. Because model pricing, context windows, and performance profiles change over time, the pipeline avoids hard-coding model calls into the core ingestion logic. Instead, a swappable adapter interface abstracts the rewriter module, allowing different LLM providers to be plugged in without modifying the data collection pipeline.
Fault-Isolated Execution
The background worker enforces strict fault isolation across all incoming data streams. Every ingested item executes in an isolated evaluation block:
- Item-level containment: If an API call times out, returns an invalid status, or encounters a rate limit, the error is written to that item's execution log in PostgreSQL.
- Source resilience: One dead RSS feed, unresponsive social feed, or failed model completion never stops the background loop from processing the remaining ~280 items in the daily queue.
Post-Generation Validation
Raw model output is never passed directly to the publishing layer. Before an entry can become an editorial draft, a post-generation validation step inspects the response against strict criteria:
- URL and citation integrity: The validator verifies that the canonical source URL remains intact. If the model hallucinates an alternative URL, drops the reference link, or introduces unauthorized external links, the draft is rejected.
- Structural completeness: Responses must parse cleanly into expected schema fields: a headline, a factual summary, and primary entity tags.
- Content boundaries: Incomplete summaries, repetitive generation loops, or responses containing model refusal text are immediately discarded.
Want a content pipeline that pulls, drafts and distributes — with you approving what goes live? WEB3 Build Studio builds AI automation on top of web apps from $2,500 through /#/contact.
Database Isolation with PENDING_REVIEW
Any item that clears the validation layer is committed to the PostgreSQL database via Prisma 6 with the PENDING_REVIEW status:
const draft = await prisma.newsItem.create({
  data: {
    title: validatedOutput.title,
    summary: validatedOutput.summary,
    sourceUrl: item.canonicalUrl,
    status: 'PENDING_REVIEW',
  },
});
The public Next.js 15 App Router frontend is hardcoded to query exclusively for records where status: 'PUBLISHED'. Because the public views cannot access or display rows marked PENDING_REVIEW, no unverified AI generation can reach the public sites without explicit human authorization.
Human Review: Telegram Review Cards and One-Tap Approvals
Crypto markets operate continuously, but forcing an editor to sit in front of a desktop content management system creates an operational bottleneck. To resolve this without sacrificing editorial standards, the system keeps every processed item in a PENDING_REVIEW state—a database status that the public sites never display—and pushes real-time review cards directly into a private Telegram moderation chat.
Inline Telegram Moderation
The background worker formats each validated draft into a concise review card. Attached directly to the card is an inline keyboard wired to Telegram bot callback queries. An editor reviewing incoming news on a phone can process a story with one tap:
- Approve: Updates the status from
PENDING_REVIEWto approved, queueing the article for immediate publication on the site and scheduling it for social distribution. - Reject: Marks the draft as rejected and archives it in PostgreSQL, halting all distribution loops.
- Edit: Triggers a bot prompt to accept corrected copy directly via reply message, or generates a direct link to the desktop editor.
The Web Administration Fallback
While mobile inline buttons handle straightforward approvals, complex stories sometimes require structural changes or manual verification against the original source text. The Next.js web application provides an administrative news review queue as the desktop fallback.
This admin view displays all pending items alongside source metadata, raw incoming payloads, and language tags. Editors can rewrite text in a rich editor, adjust SEO slugs, or discard faulty items in batches.
Routing review queues through Telegram bridges real-time mobile availability with strict human control. Setting up this workflow relies on lightweight bot infrastructure listening to callback queries and updating backend records. Teams looking to implement similar review loops can consult our guide on Telegram bot development cost, where Telegram bot builds start from $300 with dedicated monthly hosting from $59.
Multi-Channel Distribution: Telegram Channels and X
Once an editor approves a draft in the review queue, the publishing pipeline initiates distribution across both web and social endpoints. Ingestion, review, and broadcasting operate as decoupled routines, allowing distribution workers to execute without blocking incoming source processing or editorial queues.
Approved news items dispatch immediately to each platform's public Telegram channel, while an independent worker broadcasts queued updates to X on a scheduled 15-minute dispatch cycle.
Broadcaster Mechanics and Reach
Distributing directly to Telegram is essential for crypto audiences. According to data reported by TechSpot, Telegram passed 1 billion monthly active users in March 2025. In the Web3 sector, Telegram channels function as primary real-time news desks rather than secondary alert feeds.
Each broadcast payload is formatted specifically for its destination platform:
- Telegram Channels: Formatted with clean Markdown, concise lead summaries, contextual tags, and direct links pointing back to CryptoResearch.news or Blockblatt.com.
- X Feeds: Packaged to meet platform length constraints, attaching canonical story URLs and spacing deliveries through the 15-minute dispatch loop to prevent rate-limit throttling.
The German Translation and Verification Layer
Blockblatt serves a German-speaking readership, but raw machine translation often corrupts crypto reporting by over-translating industry vernacular. The pipeline runs a dedicated verification layer after drafting German copy and before any social broadcast executes.
This validator tests every post for two strict conditions:
- Industry Vocabulary Preservation: Core Web3 terminology—including terms such as staking, airdrop, and liquidity—must remain in English rather than being converted into awkward literal German equivalents.
- URL Integrity: The canonical article URL and tracking paths must remain fully intact and unmodified during the translation step.
If a translated payload fails URL validation or alters protected terminology, the dispatch worker halts the queue item and flags it for manual correction.
The Automated Blog Writer: From PDF Briefs to Long-Form Guides
Beyond real-time news aggregation, both CryptoResearch.news and Blockblatt.com require comprehensive editorial guides. To support this, the platform includes a dedicated long-form blog writer module designed to produce structured guides between 2,000 and 3,500 words. Like the short-form news pipeline, this system does not publish autonomously; it drafts content within strict technical guardrails.
PDF Text Extraction and Model Scope
The workflow starts when an editor uploads a source brief or research document as a PDF. The application processes the document locally on the server:
- Local text parsing: The Node.js server extracts the raw text directly from the PDF file.
- Isolated model calls: The raw PDF file itself is never sent to the LLM. Extracting the text locally beforehand strips file formatting overhead, controls token usage, and avoids unpredictable document-parsing errors inside the model context.
- One article per execution: The LLM receives the extracted text alongside structural prompts to generate exactly one guide per API call. Restricting the model to a single piece at a time prevents context degradation and hallucinations.
Generation Guardrails and Asset Creation
Before any generated text is saved as a usable draft, the pipeline executes validation checks:
- Duplicate checking: The module checks the generated title, target keywords, and core subject against all existing published and draft guides stored in the PostgreSQL database. If an overlap is detected, the run is flagged to prevent topic duplication and internal search cannibalization.
- Automated cover images: Once the text passes validation, the system automatically generates an optimized cover image aligned with the article's topic and taxonomy.
Paced Release Queue
Newly generated guides are saved strictly with draft status. They never go live immediately upon completion. An editor must review the draft, verify facts, and approve it.
Once approved, the system does not dump multiple long-form articles onto the site at the same time. Instead, approving a guide books a slot in an automated publishing schedule. A background cron worker checks this queue hourly, releasing approved guides at a measured pace of at most one per hour, capped at a maximum of 15 articles per day per site. This pacing protects crawl budgets and maintains a steady indexation rate for search engines.
Real-Time Data Pages: Liquidations and Exchange Wallets
Editorial analysis alone is rarely enough for a modern crypto platform. When sharp market moves happen, readers seek immediate context: where leverage was flushed and whether capital is entering or exiting centralized venues. Integrating live market telemetry directly into CryptoResearch.news and Blockblatt provides hard reference data alongside reporting without sending visitors elsewhere.
Liquidation Tracking Architecture
To display forced margin closures across major derivatives venues, the platform uses dedicated ingestors tailored to each exchange's interface:
- Binance and Bybit: Sustained WebSocket connections ingest liquidation orders in real time as they execute on-chain or on-book.
- OKX: Handled via scheduled REST polling cycles to collect aggregated liquidation summaries without maintaining persistent socket connections.
| Exchange | Connection Type | Metric Tracked |
|---|---|---|
| Binance | WebSocket stream | Real-time liquidation orders (symbol, side, size, price) |
| Bybit | WebSocket stream | Real-time contract liquidation executions |
| OKX | Scheduled REST polling | Periodic liquidation aggregates and volume totals |
Exchange Reserve Snapshots
Alongside derivative liquidations, the platform monitors stablecoin reserves. Using Etherscan API endpoints, automated workers take periodic snapshots of USDT and USDC token balances across major exchange reserve wallets. This gives readers an ongoing view of verifiable stablecoin reserves held on Ethereum across primary centralized trading venues.
Autonomous Background Routines
These tracking systems operate completely detached from editorial workflows and content generation:
- Process Isolation: Telemetry workers run as autonomous background routines. High liquidation volume or socket reconnect cycles never block editorial ingestion passes or model validation queues.
- Database Decoupling: Parsed liquidation events and wallet balances update dedicated PostgreSQL tables independently via Prisma.
- Cached Delivery: The Next.js 15 frontend queries indexed PostgreSQL records rather than hitting third-party APIs during user requests, maintaining fast page loads and avoiding rate limits.
Production Stack, Hosting Architecture, and Build Pricing
Modern Web Stack
CryptoResearch.news and Blockblatt run on a typed production foundation:
- Frontend & App Framework: Next.js 15 (App Router) with React 19.
- Database & Typing: TypeScript across the entire codebase, using Prisma 6 to query PostgreSQL for content records, scheduled passes, and dispatch states.
Decoupled Hosting Architecture
To maintain responsiveness without hitting serverless execution limits, the platform uses a decoupled infrastructure. Public frontends run on Vercel, providing edge delivery, fast page loads, and static asset caching for readers.
All backend ingestion routines, dispatch workers, and cron tasks run independently on the studio's own dedicated Linux servers. Ingestion passes, Telegram polling every 3 minutes, and liquidation feeds execute continuously without cold starts or Vercel function timeouts. To read more about this setup, see our guide on how we run our apps on our own server.
Studio Build Pricing
WEB3 Build Studio provides fixed-price engineering without agency handoffs:
- Web App / SaaS MVP: From $2,500 (AI features and custom API integrations cost extra).
- Telegram Bot: From $300 (standard tiers $500–$900).
- Monthly Hosting & Care: From $99/month for Web Apps and SaaS on our own servers, including SSL, daily backups, monitoring, and regular maintenance.
Information System Notice
All editorial articles, automated drafts, and real-time market data pages represent technical information systems and do not constitute financial, investment, or legal advice.
Build Your Next System
If you are planning an AI-assisted media platform, Telegram automation, or custom Web3 application, we design and deploy production-ready systems tailored to your workflow. Explore our services at WEB3 Build Studio or submit your specifications directly through our project brief form.
Frequently Asked Questions
Can the system publish without an editor? No. Drafts are set to PENDING_REVIEW upon creation and never appear publicly until approved by an editor through the admin dashboard or Telegram review cards.
Is the LLM provider locked in? No. The rewriter component is modular. While Google Gemini is used in this deployment, the validation layer supports swapping to alternative model APIs without altering the ingestion or review pipelines.
Frequently asked questions
Is AI-rewritten news allowed and safe for SEO?
Search engines evaluate original, accurate, and structured information rather than penalizing AI generation outright. Simply scraping and spinning third-party text creates duplicate content issues and indexation penalties. A production-ready pipeline uses AI models to extract verified facts, structure key points, and synthesize original summaries with proper source attribution. Pairing automated drafts with human verification ensures factual accuracy and clean technical metadata. To protect search performance, focus on original framing, verifiable context, and clean schema markup rather than raw republishing. Content attribution and copyright regulations vary across jurisdictions; this operational guidance is technical in nature and does not constitute legal advice.
How do you avoid duplicate stories from many sources?
Crypto news outlets frequently republish identical press releases simultaneously. To prevent duplicate stories, an ingestion pipeline normalizes incoming data from RSS feeds and APIs into a central PostgreSQL database. A deduplication layer converts titles, key entities, and timestamps into text fingerprints or semantic vector embeddings. When a new feed arrives, the system queries existing entries within a rolling time window. If the similarity score crosses a defined threshold, the pipeline clusters the item under an existing event rather than generating a duplicate draft. This aggregates multiple source perspectives into a single story while keeping the publication queue clean and relevant.
Why keep a human in the loop if AI can write the article?
Full automation introduces editorial and factual risks, especially in crypto and financial media where protocol names, contract addresses, and ticker symbols can easily be conflated. While an AI pipeline handles data ingestion, entity extraction, and draft creation, an editor provides essential quality control. Through an administrative dashboard, a reviewer can approve, modify, or reject generated content within seconds. Human oversight eliminates model hallucinations, checks that source attributions are valid, and ensures the tone matches editorial standards before publication. This hybrid workflow delivers the operational speed of automated systems without sacrificing credibility or accountability.
How does auto-posting to a Telegram channel work?
Auto-posting relies on the Telegram Bot API connected to a backend publishing worker built with Node.js and TypeScript. Once an article is approved in the database, an event triggers the publishing queue. The service formats the headline, summary, and canonical link into Telegram-compatible Markdown or HTML, attaches the featured graphic, and transmits the payload through an authenticated bot with channel administrative privileges. The background worker handles API rate limits, logs message IDs back to PostgreSQL for future reference, and can append inline interactive buttons that point readers back to the website.
Can one pipeline serve two languages?
Yes. A single ingestion pipeline can distribute extracted facts to language-specific generation prompts. For systems like CryptoResearch in English and Blockblatt in German, the engine collects source data once, then executes parallel model tasks to create localized copy tailored to each market's voice. The backend stores content records with locale tags in PostgreSQL, while the Next.js frontend renders localized routes and structured metadata for each site. Telegram distribution workers can then push localized updates to their respective language channels, eliminating redundant ingestion infrastructure while maintaining distinct editorial feeds.
What does an AI news platform cost to build and run?
At WEB3 Build Studio, a custom web app or SaaS MVP starts from $2,500, with standard implementations between $4,000 and $7,000, and pro tiers from $9,000. Exact pricing depends on ingestion sources, custom AI pipelines, and editorial tooling, which are scoped at a fixed price after a scoping call. Starting prices include design, build, deployment, and 30 days of bug fixes; AI integrations and external services cost extra. Monthly hosting and care on the studio's servers starts from $99, covering hosting, SSL, daily backups, monitoring, and routine maintenance. Third-party AI API usage scales with volume. Review starting options at /#/home/pricing.